Aiming for Perfect ImageNet-1k: The Reannotation Project
ImageNet-1k has long served as the gold standard for evaluating visual recognition models. As models improve, subtle yet impactful issues in its labels, class definitions, and structure become increasingly consequential. This page gathers our ongoing research efforts to identify, analyze, and correct the dataset — from a detailed audit of known flaws, to benchmarking state-of-the-art models on corrected variants, to a full-scale reannotation.
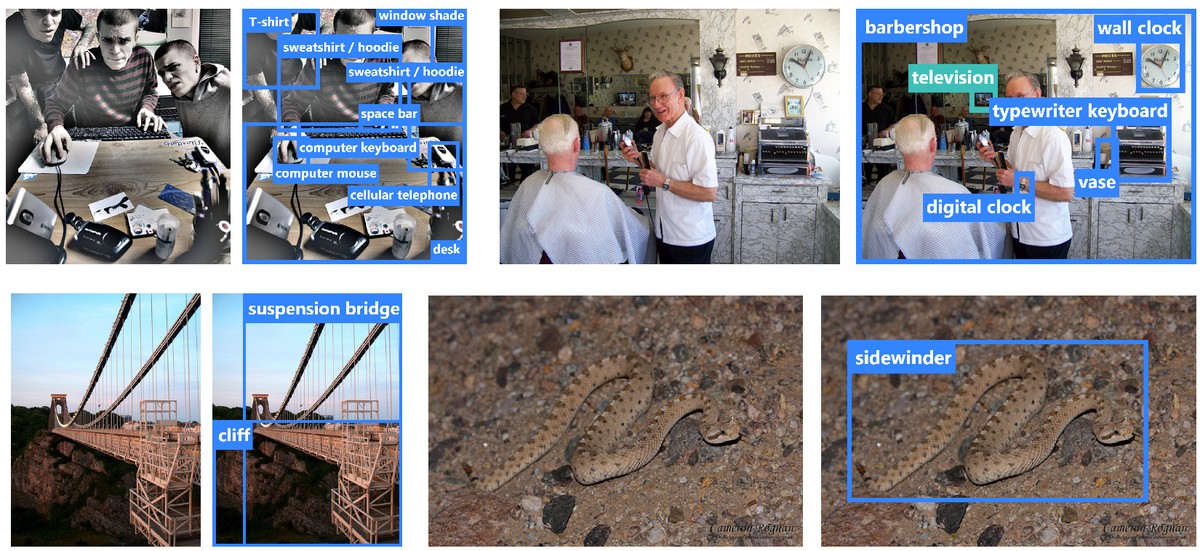
A comprehensive reannotation of the full ImageNet-1K validation set, addressing label errors, ambiguous class definitions, and multi-label instances identified through our prior analysis. The result, ReImageNet, provides a cleaner, more reliable evaluation benchmark for the community.
@article{volkov2026imagenet,
  title   = {Doomed to Re-Annotate, Forever:
             The {ImageNet} Story},
  author  = {Volkov, Illia and Kisel, Nikita and
             Mishkina, Tetiana and
             Janouskova, Klara and Matas, Jiri},
  journal = {arXiv preprint},
  year    = {2026},
  url     = {https://arxiv.org/abs/2608.13783}
}


A comprehensive analysis of ImageNet-1K's known issues: incorrect labels, overlapping and ambiguous class definitions, training–validation domain shifts, duplicate images, and problems with ILSVRC class selection. A starting point for the broader reannotation effort.
@article{kisel2025flaws,
  title   = {Flaws of {ImageNet}, Computer Vision's
             Favorite Dataset},
  author  = {Kisel, Nikita and Volkov, Illia and
             Hanzelkov{\'a}, Kate{\v{r}}ina and
             Janouskova, Klara and Matas, Jiri},
  journal = {{ICLR} 2025 Blogpost Track},
  year    = {2025},
  url     = {https://klarajanouskova.github.io/ImageNet/blog/}
}

We benchmark multimodal large language models as image classifiers on ImageNet-1K and a partially reannotated variant, revealing how annotation noise affects model rankings and benchmark reliability — and the advantage MLLMs hold over discriminative models in handling label ambiguity.
@article{kisel2025multimodal,
  title   = {Multimodal Large Language Models as Image Classifiers},
  author  = {Kisel, Nikita and Volkov, Illia and
             Hanzelkov{\'a}, Kate{\v{r}}ina and
             Janouskova, Klara and Matas, Jiri},
  journal = {arXiv preprint},
  year    = {2025},
  url     = {https://arxiv.org/abs/2603.06578}
}


We evaluate dual-encoder vision–language models for image classification, examining text-guided and vision-only approaches. We analyse key performance factors — prompt design, class diversity, k-NN count, reference set size — and introduce a learning-free fusion method based on per-class precision, tested on ImageNet-1K and corrected variants.
@inproceedings{volkov2025image,
  title     = {Image Recognition with Vision and Language
               Embeddings of {VLMs}},
  author    = {Volkov, Illia and Kisel, Nikita and
               Janouskova, Klara and Matas, Jiri},
  booktitle = {British Machine Vision Conference ({BMVC})},
  year      = {2025},
  url       = {https://arxiv.org/abs/2509.09311}
}